Home

When Should Businesses Choose LangChain for AI Agent Development?

When Should Businesses Choose LangChain for AI Agent Development?

Join our Newsletter!

Langchain for AI Agent Developement

Every business leader today is asking the same question in some form: how do we bring AI agents into our workflows without breaking what already works? This is exactly where LangChain AI agent development enters the conversation. As companies move past simple chatbots and into agents that can plan, reason, and take action, choosing the right framework becomes a decision that shapes the entire product roadmap.

Key Takeaways

  • 01 LangChain simplifies complex agent workflows. It reduces the need to build custom logic for memory, tools, and multi-step reasoning from scratch.
  • 02 It fits best when tasks involve multiple steps. Simple single-response bots rarely need it, but workflows involving tools, memory, and data retrieval benefit significantly.
  • 03 Multi agent architecture supports scalability. Splitting tasks across specialized agents improves accuracy and makes systems easier to manage as they grow.
  • 04 Use cases span far beyond customer support. Businesses are applying it to document processing, internal knowledge assistants, and workflow automation across departments.
  • 05 The right framework depends on your actual needs. LangChain works well for teams that want faster development without sacrificing flexibility or control.

Not every project needs the same tools, and not every AI initiative should default to the most popular option on the market. Some businesses need speed; others need control, and many need both at once. In this blog, we are going to explore when LangChain genuinely makes sense for your business and when it might not be the right fit.

Looking to build scalable AI agents with LangChain? At Mindpath, we provide AI agent development services that integrate seamlessly with your existing business systems.

How AI Agents are Shaping Business in 2026?

In 2026, AI agents can understand context, retrieve live data, use external tools, and make decisions with minimal human input. Frameworks like LangChain help developers build these complex workflows by connecting LLMs with memory, tools, APIs, and decision logic, making it easier to develop reliable AI agents beyond simple prompt-and-response interactions.

What is the LangChain Framework and How Does It Work?

LangChain is a toolkit that connects prompts, AI models, memory, and external data sources to build AI agents. It breaks tasks into smaller steps, helping agents select tools, retrieve relevant information, and generate accurate responses while reducing the need for custom code.

1. Chains Connect Logic in Sequence

A chain links one action to the next, so the output of a search step can feed directly into a summarization step without manual handoffs.

2. Memory Keeps Context Alive

The framework can retain earlier parts of a conversation, which means the agent does not lose track of what a user already said.

3. Tool Integration Extends Capability

LangChain lets an agent call APIs, databases, or search engines, turning it from a text generator into something that can actually perform tasks.

4. Prompt Templates Standardize Behavior

Teams can define reusable prompt structures, which keeps agent responses consistent across different use cases.

Key LangChain Use Cases Businesses Are Adopting

Once a team understands the basics, the next question is usually where it actually fits into daily operations. There are several langchain use cases that have become common across industries, and most of them share one thing in common: they involve multiple steps that would be difficult to manage with a single prompt alone.

1. Customer Support Automation

Agents can pull order details, check policies, and respond with accurate, personalized answers instead of generic scripted replies.

2. Internal Knowledge Assistants

Employees can ask questions and get answers pulled directly from internal documents, wikis, or databases, cutting down time spent searching.

3. Document Processing and Summarization

Long contracts, reports, or research papers can be broken down, analyzed, and summarized in a fraction of the time it would take a person.

4. Data Retrieval and Analysis Agents

Businesses use LangChain to connect language models with structured data sources, allowing agents to answer questions that require real-time information.

5. Workflow Automation Across Tools

Agents can trigger actions in other software, such as updating a CRM record or sending a notification, based on a single instruction.
Langchain for ai agent development

When to Use LangChain for AI Agent Development?

Deciding when to use LangChain really comes down to the complexity of what you are trying to build. A simple FAQ bot does not need this level of infrastructure. But once a project involves multiple tools, ongoing context, or decision-making across several steps, LangChain starts to make a lot more sense.

1. Your Project Needs Multiple Tools

If your agent has to search, calculate, and then write a response, LangChain manages that coordination cleanly.

2. You Need Memory Across Interactions

Businesses building assistants that remember previous conversations benefit from LangChain’s built-in memory handling.

3. You Are Integrating With Several Data Sources

When an agent needs to pull from a database, an API, and a document store in one flow, LangChain simplifies that connection.

4. You Expect the System to Scale

As agent complexity grows, LangChain’s modular structure makes it easier to add new capabilities without rewriting everything.

5. Your Team Wants Faster Development Cycles

Because so many components already exist, teams often build and test working prototypes much faster than building everything from the ground up.

Understanding LangChain Multi-Agent Architecture

As businesses take on more ambitious projects, a single agent handling everything often becomes a bottleneck. This is where langchain multi agent architecture becomes relevant. Instead of one agent trying to do research, analysis, and writing all at once, the work gets split across specialized agents that each handle a specific part of the task and then hand off their results to the next one.

1. Specialized Roles Improve Accuracy

A research agent focused only on gathering data tends to perform better than one agent trying to do everything at once.

2. Parallel Processing Saves Time

Multiple agents can work on different parts of a task simultaneously instead of waiting in a single sequence.

3. Easier Debugging and Monitoring

When something goes wrong, it is far easier to trace the issue back to one specific agent rather than digging through a single massive workflow.

4. Better Scalability for Complex Systems

As business needs grow, new agents can be added to the architecture without disrupting the ones already working well.

This kind of setup is becoming increasingly common for businesses that are serious about long-term LangChain AI agent development, especially when the use case involves research, reporting, or any workflow with distinct stages.

Is LangChain the Right Choice for Your Business?

Choosing a framework is never just about following what is popular. It comes down to what your business actually needs to accomplish, how complex your workflows are, and how much your team wants to build versus manage.

LangChain has earned its place as one of the strongest options for teams building agents that need to reason, remember, and act across multiple steps. For businesses working on genuine LangChain AI agent development rather than a simple one-off script, it offers a level of structure and flexibility that is hard to match with a lighter tool.

At Mindpath, we work closely with businesses to design and build AI agents that fit their actual operations, not a generic template. Whether you need a single well-trained assistant or a full multi-agent system handling different parts of your workflow, our team brings the technical depth to build it right. We provide AI agent solutions that are tailored to your data, your tools, and your goals, so the technology actually solves the problem you started with.


Building Your Agents With LangChain?

We turn LangChain prototypes into production-ready systems.

Frequently Asked Questions

LangChain provides ready-made components for memory, tool integration, and chaining logic. This saves development time and reduces the chance of errors compared to building every piece manually.
Yes, small businesses can use LangChain for tasks like customer support or internal document search. The framework scales down well for simpler, single-purpose agents too.
No, LangChain supports much more than chatbots. It is widely used for data retrieval, document analysis, workflow automation, and multi-step decision-making tasks.
Developers with Python experience usually pick it up fairly quickly. The learning curve depends on how complex the agent workflow needs to be.
LangChain is designed to be flexible and supports integration with multiple language models, not just one specific provider, giving businesses more freedom in their tech stack.

Support Is One Click Away

Featured Posts

Related Post

Frontend and Backend

Building a scalable business application requires more than an attractive user interface or a powerful server. Businesses need both layers to work together effectively. The frontend and backend serve different purposes, but their integration influences application performance, security, usability, and the ability to support growing business needs.

The frontend manages what users see and interact with, while the backend handles business logic, data processing, authentication, and communication with databases and other services. When these layers are designed around clear responsibilities and reliable communication, businesses can build applications that are easier to maintain, extend, and scale.

Key Takeaways

  • 01
    The frontend delivers the user interface and interactions, while the backend manages business logic, data access, and server-side processing.
  • 02
    APIs enable the frontend and backend to exchange data and coordinate application workflows.
  • 03
    Caching, efficient data handling, asynchronous processing, and performance monitoring help applications remain responsive as usage grows.
  • 04
    Security requires coordinated controls across both layers, including server-side authorization, input validation, secure sessions, and safe data handling.
  • 05
    Choosing an appropriate architecture depends on business requirements, expected traffic, system complexity, budget, and long-term maintenance needs.
Planning a scalable business application? Explore Mindpath’s full-stack development services to discuss your application architecture, integration requirements, and development goals.

What are Frontend and Backend Development?

What Is Frontend Development?

Frontend development focuses on the parts of an application that users see and interact with. It includes page layouts, navigation, buttons, forms, dashboards, visual elements, and responsive behavior across different screen sizes.

Frontend developers use technologies such as HTML, CSS, and JavaScript, along with libraries and frameworks such as React, Angular, and Vue.js. Their work helps ensure that users can navigate the application, complete tasks, and access information through a clear and consistent interface.

For a business application, the frontend might include a customer dashboard, a product catalog, an account settings page, or an employee management interface. The design should consider usability, accessibility, responsiveness, and the needs of the intended users.

What Is Backend Development?

Backend development focuses on the server-side systems that process requests, enforce business rules, manage data, and connect applications with other services. It supports the operations users rely on when they sign in, submit a form, place an order, or retrieve information.

Backend developers may use technologies such as Node.js, Python, Java, PHP, and Ruby, alongside databases such as PostgreSQL, MySQL, and MongoDB. The appropriate technology depends on the application’s data model, performance requirements, integrations, team expertise, and operational constraints.

For example, when a customer submits an order, the backend can validate the request, check product availability, apply business rules, coordinate payment processing, and store the order record. The frontend then displays the relevant result to the customer.

To understand how the different development roles compare, read our guide to frontend vs. backend developers.

How Frontend and Backend Work Together to Build Scalable Applications

The frontend and backend communicate to turn user actions into application operations. The frontend collects input and presents results, while the backend validates requests, applies business logic, and retrieves or updates data. This interaction must be reliable, secure, and efficient if the application is expected to support more users and more complex workflows.

1. API Communication

Application programming interfaces (APIs) provide defined ways for the frontend and backend to exchange information. The frontend sends requests to backend endpoints, and the backend returns data or a response indicating the result of the operation.

REST APIs and GraphQL are two common approaches to application data communication. Depending on the requirements, systems may also use WebSockets or other communication patterns for real-time updates.

For example, an ecommerce frontend may request product information, submit cart updates, and retrieve order details through APIs. The backend checks permissions, validates input, applies business rules, and returns the appropriate response.

Clear API contracts help frontend and backend teams develop independently while reducing integration problems. Teams should document expected data formats, authentication requirements, error responses, and versioning policies.

2. Architecture That Supports Growth

An application’s architecture determines how its components are organized and how they communicate. A modular monolith can be a practical starting point for many business applications because it keeps related functionality in one deployable system while maintaining clear internal boundaries.

For more complex systems, a microservices architecture separates selected business capabilities into independently deployable services. For example, an application might have separate services for payments, user accounts, notifications, and product management.

Microservices can allow teams to scale or deploy specific services independently, but they also introduce additional operational complexity, network communication, monitoring, and data consistency challenges. Businesses should choose this approach when its benefits justify the extra effort rather than treating it as a requirement for every scalable application.

3. Asynchronous Processing

Some application operations take longer than a typical user interaction should require. Examples include generating reports, processing large files, sending bulk notifications, and running complex calculations.

Asynchronous processing allows an application to handle these tasks without making users wait for the entire operation to finish within the original request. A backend may place work in a queue and process it through a background worker while the frontend displays a pending status.

For example, a business dashboard could let a user request a large report, return a confirmation, and notify the user when the report is ready. The implementation should provide clear status updates, error handling, and a way to retry failed operations when appropriate.

4. Efficient Data Handling

The amount and structure of data exchanged between the frontend and backend can affect response times, bandwidth usage, and application responsiveness. Sending more data than a screen requires can increase processing costs and make interfaces feel slow.

Developers can improve data handling by selecting only the necessary fields, using pagination for large result sets, applying suitable filtering and sorting, and avoiding unnecessary API requests. Caching can also reduce repeated work when the data and freshness requirements allow it.

For example, an employee directory with thousands of records can return a limited page of results rather than sending every employee record to the browser. The frontend can request additional pages as users navigate the directory.

Data validation should take place on the backend even when the frontend already checks user input. Client-side validation improves usability, but it cannot replace server-side controls.

5. Scaling Frontend and Backend Resources

As an application gains users, different parts of the system may experience different types of demand. The frontend may need efficient asset delivery and content caching, while the backend may need additional processing capacity, database optimization, or more workers.

Frontend resources can often be delivered through a content delivery network (CDN), while backend services may scale by adding instances or allocating additional computing resources. Database scaling strategies depend on query patterns, data volume, consistency requirements, and the chosen database technology.

Independent scaling can help teams respond to specific bottlenecks, but it requires suitable architecture, monitoring, deployment practices, and capacity planning. A well-designed application scales according to measured demand rather than adding infrastructure without understanding the workload.

Want to understand how frontend, backend, and full-stack roles fit together? Read our guide to frontend vs. backend vs. full-stack developers.

6. Secure Communication and Access Control

Security depends on the way the frontend, backend, APIs, databases, and connected services work together. The frontend can provide a secure and understandable sign-in experience, but the backend must enforce authentication and authorization before allowing access to protected resources.

For example, hiding an administrative button in the frontend does not prevent an unauthorized user from attempting to call the underlying API. The backend must verify the user’s permissions for each protected operation.

Important practices include:

  • Use HTTPS to protect data transmitted between clients and services.
  • Validate and sanitize untrusted input at appropriate system boundaries.
  • Enforce authentication and authorization on the backend.
  • Store passwords and secrets using suitable security practices; never expose private credentials in frontend code.
  • Use parameterized database queries or equivalent protections against injection attacks.
  • Manage sessions, tokens, dependencies, and error messages carefully.
  • Log relevant security events while avoiding unnecessary exposure of sensitive information.

Security should be considered throughout development rather than added only before launch. Regular testing, dependency updates, access reviews, and incident-response planning help maintain protection as the application evolves.

For additional guidance, read our article on application security best practices.

7. State Management and Data Consistency

Frontend applications often need to manage information such as the current user, selected filters, form values, shopping cart contents, and data retrieved from APIs. State management helps components access and update the information they need in a predictable way.

For smaller applications, built-in React state and context may be sufficient. Larger applications may benefit from dedicated state management or data-fetching libraries, depending on their complexity.

It is important to distinguish temporary frontend state from persistent backend data. The frontend may cache a response or optimistically display an update, but the backend remains responsible for enforcing business rules and persisting authoritative records.

When multiple users can update the same data, the application may also need conflict handling, refresh strategies, or real-time updates to keep information consistent.

8. Performance Optimization Across Both Layers

Application performance is a shared responsibility. A frontend can be slowed by large JavaScript bundles, unoptimized images, excessive rendering, or unnecessary network requests. A backend can be slowed by inefficient database queries, expensive computations, external service delays, or insufficient capacity.

Frontend optimization may include:

  • Reducing unnecessary JavaScript and loading code when it is needed.
  • Optimizing images, fonts, and other static assets.
  • Using appropriate caching and minimizing redundant requests.
  • Measuring real user experience and addressing accessibility issues.

Backend optimization may include:

  • Analyzing database queries and adding appropriate indexes.
  • Caching frequently requested data where safe and useful.
  • Moving suitable long-running operations to background workers.
  • Setting sensible timeouts, retries, and resource limits for external services.

Teams should measure performance across the full request path. This helps them identify whether delays originate in the browser, network, API, database, or an external dependency.

Read our guide to optimizing React performance for large applications for related frontend performance considerations.

9. Load Balancing and Traffic Management

Load balancing distributes incoming requests across multiple available servers or service instances. It can help a backend handle higher traffic volumes and reduce dependence on a single instance, provided the application and its infrastructure are configured appropriately.

For example, a business application may receive a spike in traffic during a product launch or a promotional campaign. A load balancer can distribute requests across healthy backend instances while monitoring helps the team identify capacity issues.

Load balancing does not remove every bottleneck. Databases, third-party services, shared storage, and application-level limits may still constrain throughput. Businesses should combine traffic management with health checks, capacity planning, suitable caching, and performance monitoring.

10. Centralized Logging, Monitoring, and Observability

When an application spans the browser, APIs, backend services, databases, and third-party systems, identifying the cause of an issue can be difficult without coordinated monitoring.

Frontend monitoring can capture JavaScript errors, failed requests, and user-facing performance issues. Backend monitoring can track API latency, error rates, resource use, database performance, and background job failures.

Centralized logs, metrics, and distributed traces help teams follow a request across different components and identify where a failure or delay occurred. Correlation IDs can help connect related events across services.

Monitoring should also include meaningful alerts and operational procedures. Teams need to know which issues require immediate attention and how to investigate them without collecting unnecessary sensitive user data.

Frontend and Backend: Key Differences

Although frontend and backend development work closely together, their main responsibilities differ. Understanding these differences helps businesses plan teams, select technologies, and define system boundaries.

Area Frontend Backend
Primary role Presents the interface and handles user interactions. Processes requests, enforces business rules, and manages data access.
Common technologies HTML, CSS, JavaScript, React, Angular, Vue.js. Node.js, Python, Java, PHP, Ruby, and other server technologies.
Typical responsibilities Layouts, navigation, forms, accessibility, and client-side state. Authentication, authorization, APIs, business logic, and data persistence.
Performance priorities Rendering, asset delivery, responsiveness, and interaction speed. API latency, database queries, processing capacity, and service reliability.
Security responsibilities Safe interface behavior, appropriate handling of client-side data, and secure communication. Server-side access control, input validation, secrets management, and data protection.

The two layers are not completely independent. Decisions about data formats, authentication, caching, rendering, and error handling affect both. Collaboration and clear technical contracts help keep the complete application reliable.

How to Choose the Right Architecture for a Scalable Business Application?

The right architecture depends on the business problem, expected traffic, data requirements, integration needs, available skills, and budget. A small internal tool may need a straightforward application structure, while a complex enterprise platform may require separate services and more advanced operational controls.

1. Define Business and User Requirements

Identify the main workflows, user groups, integrations, data requirements, and expected usage patterns. These details help determine which frontend capabilities and backend responsibilities the application needs.

2. Select Technologies Based on Project Needs

Choose frontend frameworks, backend technologies, and databases according to the required functionality, team expertise, performance targets, and maintenance expectations. Avoid selecting a complex stack solely because it is popular.

3. Define API Contracts and Data Ownership

Document the information exchanged between the frontend and backend, including request formats, responses, errors, authentication, and versioning. Clear contracts help teams work independently and reduce integration issues.

4. Plan for Security and Reliability

Design authentication, authorization, input validation, logging, backup, recovery, and monitoring into the application. Consider how the system will handle failed requests, unavailable dependencies, and unexpected traffic.

5. Scale Based on Measured Demand

Begin with an architecture that matches current requirements while preserving practical options for growth. Use monitoring and load testing to identify bottlenecks before introducing additional infrastructure or splitting the application into multiple services.

6. Plan for Maintenance and Future Enhancements

Include testing, documentation, dependency updates, deployment practices, and ongoing support in the development plan. Maintainable code and clear ownership help businesses evolve the application without making every new feature unnecessarily difficult to deliver.

Why Full-Stack Development Can Help?

Full-stack development brings frontend and backend expertise together within a development team or individual role. This can help teams coordinate interface design, API development, data handling, and integration work across the application.

For businesses, a full-stack approach can be useful when building a new product, integrating existing systems, or extending an application with new functionality. The team still needs clear responsibilities, appropriate specialization, testing, and security reviews to ensure that both layers meet their requirements.

Read more about full-stack development and how it brings frontend and backend work together.

Looking for support across the complete application lifecycle? Explore Mindpath’s full-stack development services for help with frontend development, backend systems, API integration, and application scalability.

Final Thoughts

The frontend and backend are two essential parts of a modern business application. The frontend shapes how users interact with the product, while the backend handles data, business logic, integrations, and server-side operations. Their coordination influences usability, security, performance, and maintainability.

Businesses planning scalable applications should focus on clear API contracts, efficient data handling, appropriate architecture, coordinated security controls, and reliable monitoring. The best technical approach is the one that fits the application’s actual requirements and can evolve as those requirements change.

At Mindpath, we help businesses plan and build digital products with practical development approaches. Our full-stack development services can support projects that need coordinated frontend and backend expertise, integrations, and maintainable application architecture.

Staff Augmentation vs Traditional

IT staff augmentation offers a flexible, scalable, and cost-effective alternative to traditional hiring models. It enables businesses to quickly access specialized talent, adapt to changing project needs, and optimize resource allocation without long-term commitments. This approach enhances operational efficiency, speeds up hiring processes, and supports strategic growth in dynamic markets.

Are you struggling to find the right talent for your IT projects or facing challenges with traditional hiring processes? Traditional hiring could take months, but what if there was a faster, more flexible solution? Now, with IT staff augmentation, you may satisfy your project goals fast and effectively without the long-term commitment and expense associated with traditional employment.

In today’s fast-changing business environment, companies need to scale quickly and adapt to project demands. IT staff augmentation allows businesses to add skilled professionals to their existing teams without long-term hiring commitments, making it easier to adjust resources as project needs change.

What are the traditional hiring models?

Traditional hiring models cover a range of techniques used by businesses to onboard new staff members. Here’s a short breakdown:

1. Direct Hiring

This is the most popular approach used by businesses to hire people directly for full- or part-time jobs. It includes posting job positions, evaluating applications, setting up interviews, and choosing job applicants.

2. Temporary Hiring

Businesses employ people to do certain tasks or for a set amount of time. Temporary hires are made by the company itself or through employment agencies to cover short-term positions like project-based labour or seasonal labour.

3. Contractual Hiring

Contractual hiring is employing individuals or businesses under a formal contract to do certain activities or projects. Contractors may labour for a certain amount of time until the project is finished, and they are normally compensated for their services in accordance with the conditions specified in the contract.

4. Freelancers or Independent Contractors

Businesses employ independent contractors or freelancers on a project-by-project basis. They work for themselves and supply specialized knowledge or services on demand, frequently from a distance. They are not employees.

Drawbacks of traditional hiring models

Despite being frequently employed, traditional employment strategies include several drawbacks that businesses need to consider:

1. Time and Resource Inefficiency

It might take a while and a lot of resources to advertise job positions, evaluate applications, hold interviews, and decide who gets hired. This inefficiency frequently leads to protracted spells of unemployment, which affects output and pushes back project deadlines.

2. Cost Implications

Conventional hiring includes indirect costs like pay, benefits, and overhead related to permanent workers in addition to direct expenditures like advertising, onboarding charges, and recruiting agency fees (if applicable). Budgetary constraints may be strained by these costs, especially if turnover rates are significant or if highly skilled personnel require premium pay.

3. Rigidity in Staffing

In traditional models, once employed, workers usually commit to long-term jobs that might not match project-specific requirements or changing corporate demands. This lack of adaptability may cause resources to be overextended during peak hours or underutilized during off-peak hours, which would reduce overall operating efficiency.

4. Skills and Expertise Gaps

Access to the knowledge or abilities required for specialized projects or cutting-edge technology could not always be ensured by traditional recruiting practices. Talent with specialized skills may be difficult for organizations to find and keep, which might impede innovation and competitiveness in quickly changing sectors.

Overview of IT Staff Augmentation

IT staff augmentation is a flexible outsourcing model that helps businesses quickly add skilled IT professionals to their existing teams. Instead of hiring full-time employees, companies bring in experts on a temporary or project basis to fill skill gaps and meet project goals. These professionals are typically hired through staffing agencies, freelancers, or direct contracts based on the specific expertise needed.

Key Benefits of IT Staff Augmentation

1. Flexibility and Scalability

Two key benefits of hiring more IT professionals are flexibility and scalability. IT staff augmentation lets companies quickly bring in skilled experts when needed without making long-term hiring commitments. This helps businesses adapt to changing project demands while keeping work on track. It also allows companies to scale their teams up or down as projects change, reducing costs and making it easier to expand into new markets when needed.

2. Cost-Effectiveness

Staff augmentation is a cost-effective way to access specialized talent without the high costs of traditional hiring. It reduces recruitment, onboarding, and long-term employee expenses like benefits and office space. Companies can also scale their workforce based on project needs, helping them manage budgets more efficiently.

3. Access to Specialized Talent

Access to specialized talent helps companies quickly bring in expertise they don’t have in-house. By hiring skilled professionals through agencies or direct contracts, businesses can handle technical or short-term projects without making long-term hires. This approach improves project outcomes, drives innovation, and helps companies stay competitive in fast-changing industries.

4. Faster Hiring Process

IT staff augmentation helps companies hire skilled professionals much faster than traditional recruitment. With access to pre-screened talent, businesses can quickly fill roles, start projects sooner, meet deadlines, and stay flexible while reducing hiring delays and maintaining quality.

Choosing Between IT Staff Augmentation and Traditional Hiring

Criteria IT Staff Augmentation Traditional Hiring
Flexibility High – Can scale up/down as needed Low – Fixed, long-term commitments
Cost Cost-effective, reduced overhead Higher costs, including benefits and office space
Time to Hire Fast – Quick onboarding with pre-vetted candidates Slow – Lengthy recruitment and onboarding process
Access to Talent Access to specialized, global talent quickly Limited to available local talent
Project Adaptability Easily adapt to changing project needs Rigid, less adaptable to project changes
Commitment Short-term or project-based Long-term employment contracts

Conclusion

In conclusion, IT staff augmentation helps businesses stay flexible, scale teams quickly, and access specialized talent without the commitment of traditional hiring. It improves efficiency, optimizes resources, and keeps companies competitive in a fast-changing market.

Whether you need to scale for a new project or hire specialized IT talent, Mindpath offers flexible staffing solutions tailored to your needs. Contact us today to learn how we can support your business.

Discover the advantages of IT staff augmentation over traditional hiring. Learn how it offers flexibility, cost savings, and quick access to specialized talent for your projects.
Node js libraries for AI

Businesses increasingly use artificial intelligence to improve customer experiences, automate workflows, and build more capable digital products. For teams working with JavaScript, Node.js libraries for AI provide practical ways to connect applications with machine learning models, language-processing tools, and generative AI services without rebuilding the entire technology stack.

The right approach depends on what you want to build. Some libraries support machine learning directly in JavaScript, others provide natural language processing or computer vision features, and AI service SDKs connect applications to hosted models through APIs. Understanding these differences helps development teams choose tools that fit their technical requirements, budget, and deployment environment.

Key Takeaways

  • 01
    Node.js supports AI integration through JavaScript machine learning libraries, specialized NLP tools, and SDKs for hosted AI services.
  • 02
    TensorFlow.js, Natural, and Compromise serve different needs, from model execution to text processing and language analysis.
  • 03
    AI service SDKs connect Node.js applications to hosted models, while local libraries may support inference or model development in JavaScript.
  • 04
    Library selection should account for maintenance status, compatibility, performance, licensing, privacy, and deployment requirements.
  • 05
    Businesses can combine Node.js with AI APIs or specialized model services to build chatbots, recommendations, document workflows, and other AI-enabled features.
Planning an AI-powered application? Mindpath’s AI integration services can help you evaluate integration options based on your product requirements and existing technology stack.

Why Integrate AI into Node.js Applications?

Node.js is a JavaScript runtime commonly used to build APIs, backend services, real-time applications, and web application infrastructure. Its event-driven, non-blocking I/O model can help applications manage many concurrent network operations, including requests to external AI services.

Node.js can integrate with AI in several ways. Developers can execute compatible models with JavaScript libraries, call hosted AI models through APIs, or connect to a separate inference service written in another language. The best option depends on model requirements, latency expectations, infrastructure, and the amount of control the application needs.

JavaScript’s broad use across web development can also make it convenient for teams that want to share familiar language and tooling across frontend and backend work. However, demanding model training or specialized inference workloads may be better suited to dedicated machine learning frameworks or services.

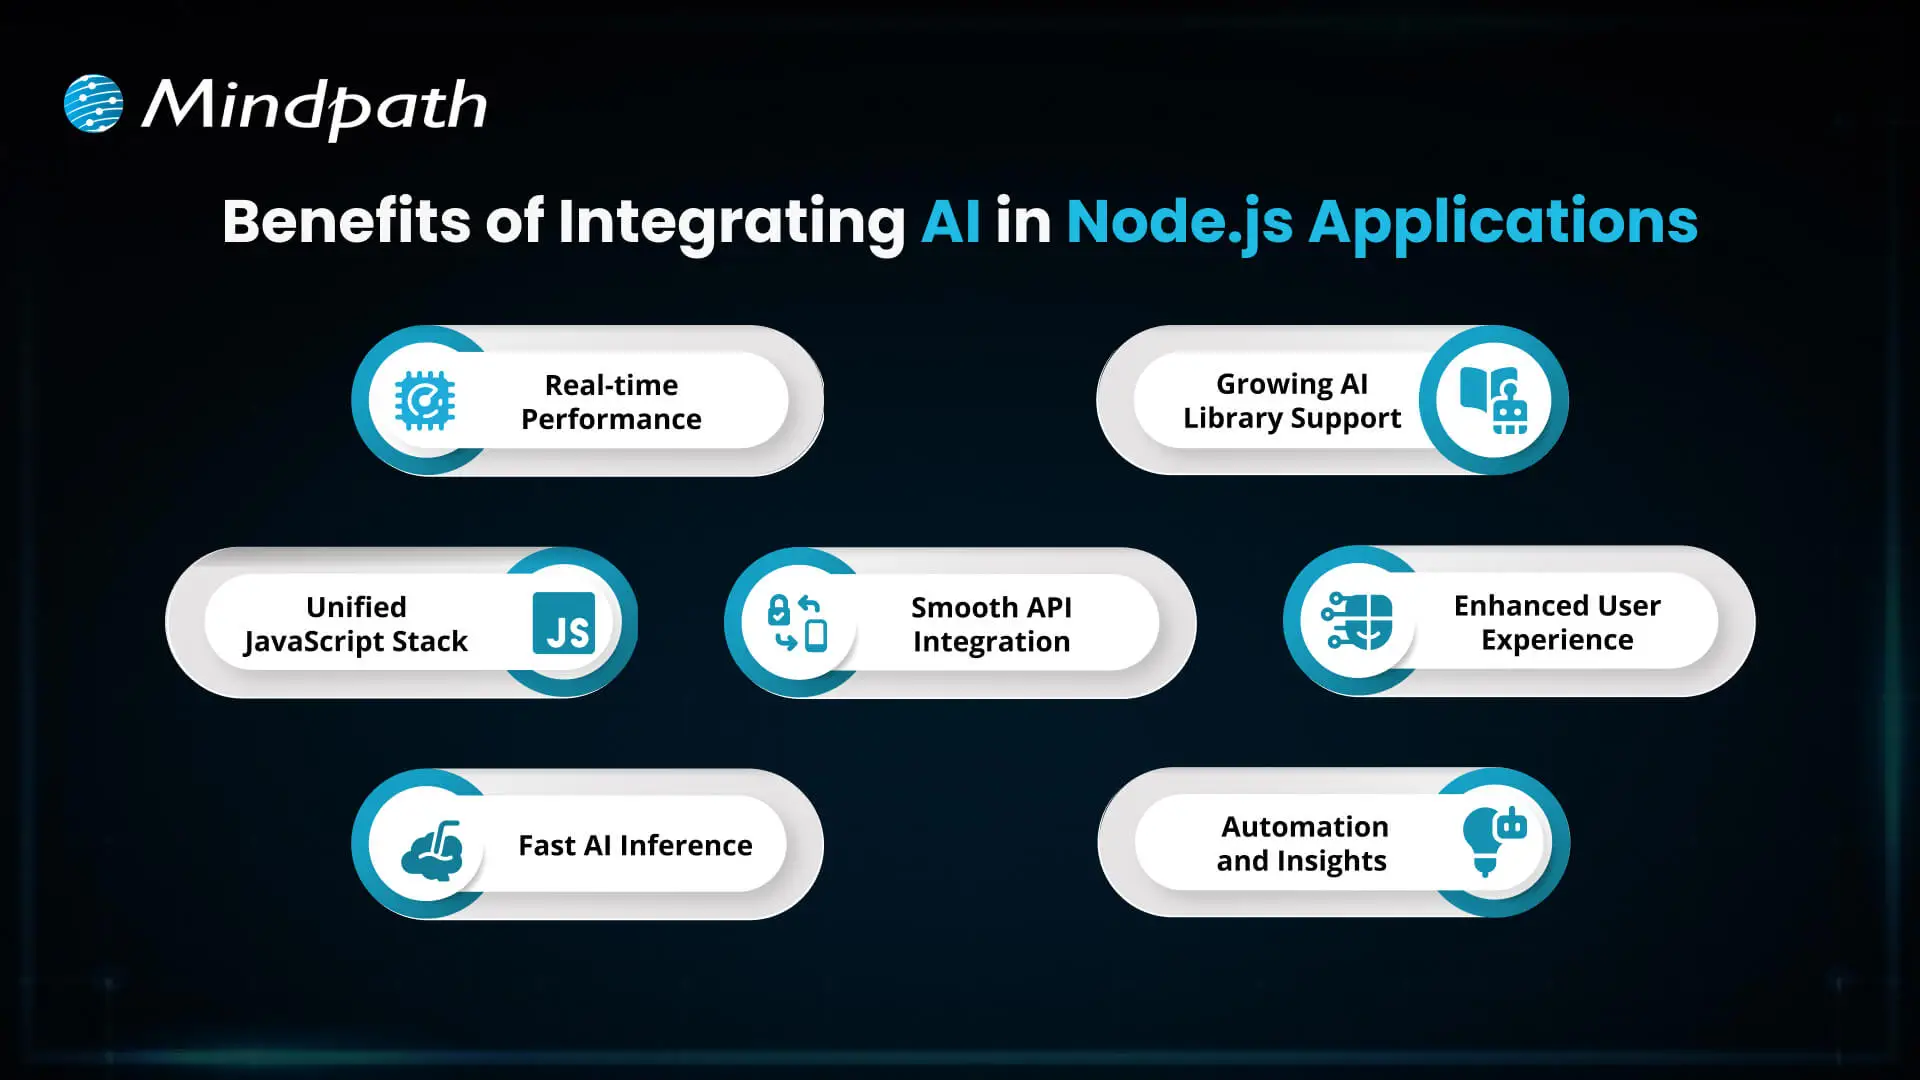
Here are some potential benefits of integrating AI into Node.js applications:

Benefits of integrating AI into Node.js applications

1. Responsive AI Features

Node.js can manage application requests and communicate with AI services asynchronously. This is useful for features such as chat interfaces, recommendation APIs, and automated document processing. Actual response times depend on the model, network, infrastructure, and application design.

2. A Familiar JavaScript Stack

Teams already using JavaScript can integrate AI functionality into their Node.js backend without necessarily introducing a separate application layer for every feature. This can simplify some development workflows, although specialized models may still require Python-based services or other infrastructure.

3. Flexible Model Execution

Depending on the model and runtime, developers can run compatible inference workloads in JavaScript or send requests to an external model endpoint. Performance should be benchmarked against the actual workload instead of assuming that Node.js or any particular library will automatically provide faster inference.

4. Integration with Existing Systems

Node.js applications can connect AI services to databases, customer relationship management platforms, content systems, and internal APIs. This makes it possible to incorporate AI into existing workflows rather than treating it as an isolated feature.

5. A Range of AI Libraries and Services

The JavaScript ecosystem includes machine learning libraries, natural language processing tools, computer vision packages, and SDKs for hosted AI services. Each category serves a different purpose, so developers should select tools based on their intended functionality and ongoing support.

6. More Context-Aware User Experiences

AI features can support conversational assistance, personalized recommendations, classification, and content analysis. Their usefulness depends on data quality, model selection, testing, and appropriate safeguards for the application.

7. Workflow Automation

AI integration can help automate tasks such as categorizing incoming requests, extracting information from documents, and routing customer queries. Teams should keep validation, monitoring, and human review in place where mistakes could have significant consequences.

Related reading: Top Node.js Libraries covers additional tools for building Node.js applications.

Top Node.js Libraries for AI Integration

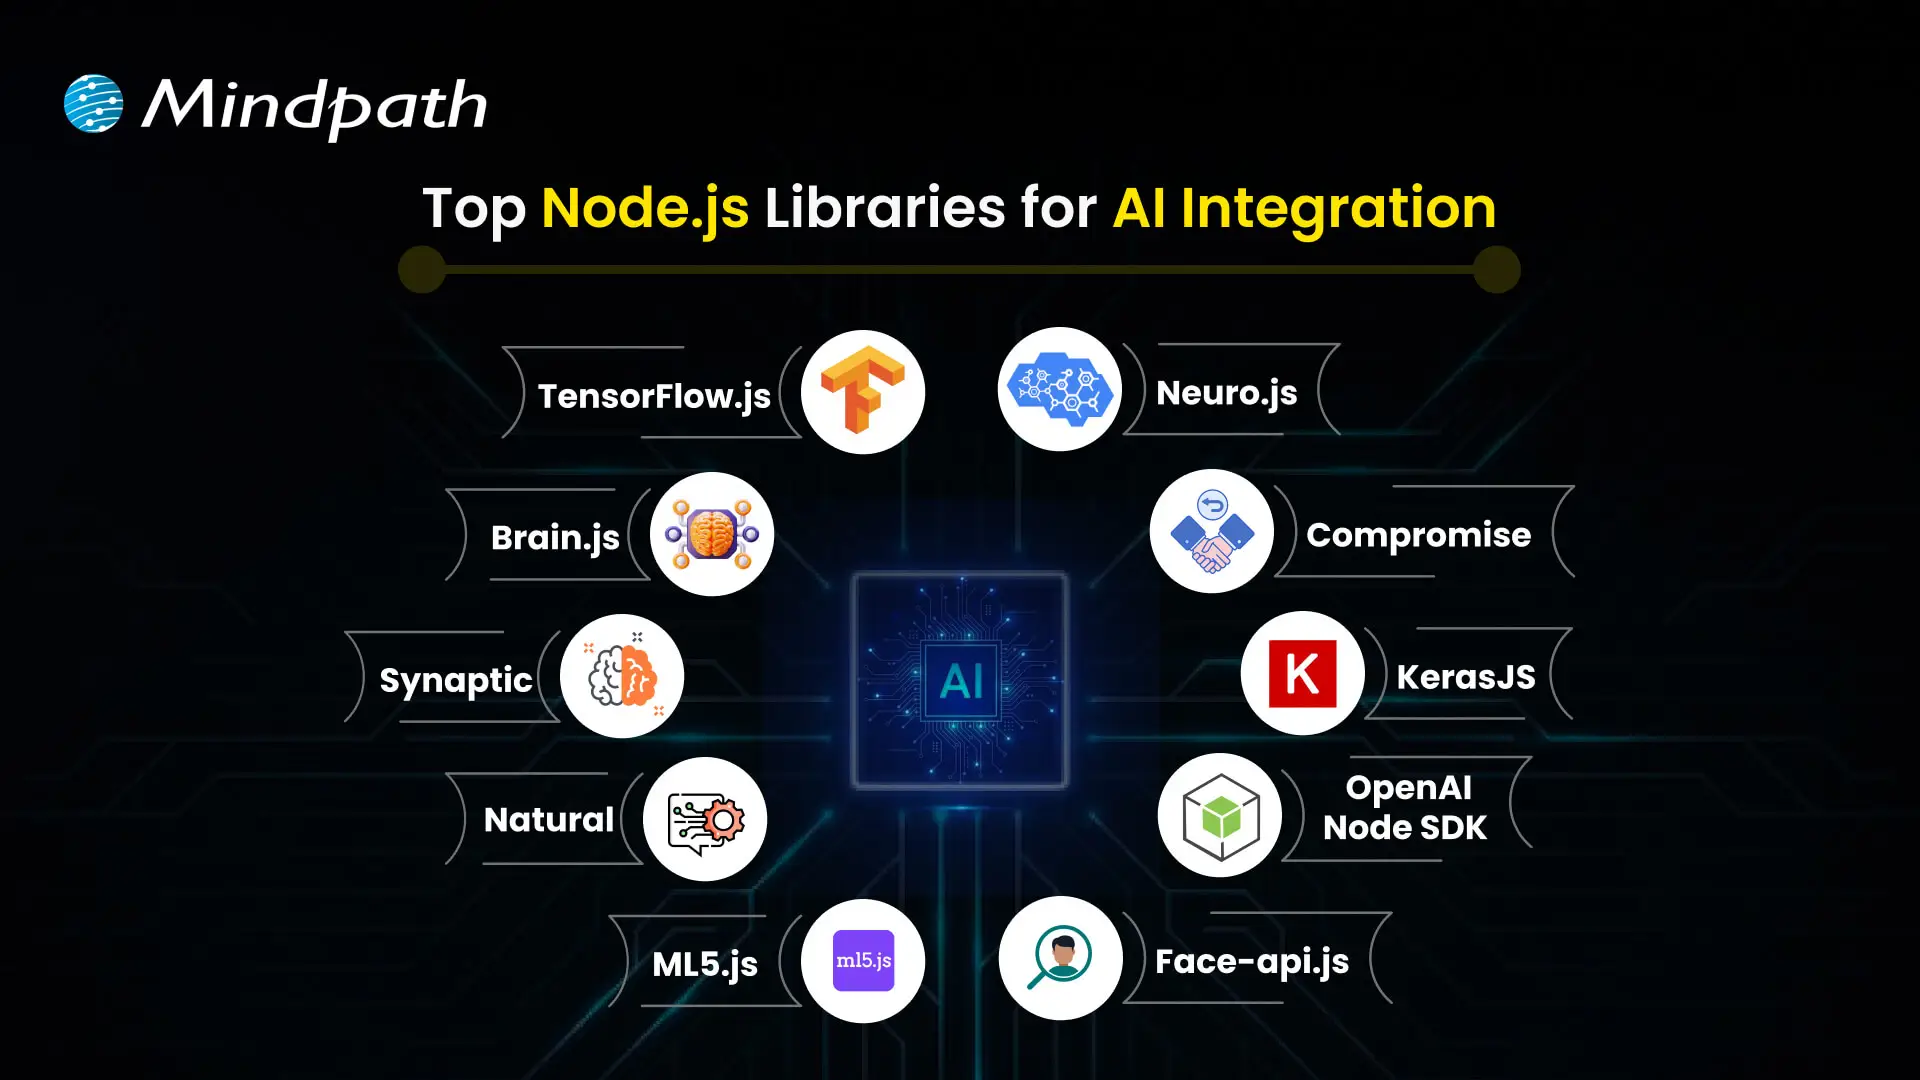
There is no single best AI library for every Node.js project. Some tools provide machine learning capabilities, others focus on text processing or computer vision, and some help applications communicate with external AI platforms. The following options cover different use cases and should be evaluated for current maintenance, compatibility, and licensing before adoption.

Node.js libraries and tools used for AI integration

1. TensorFlow.js

Best for: JavaScript-based machine learning and model inference.

TensorFlow.js provides tools for developing, training, and running machine learning models in JavaScript. It supports browser-based use and Node.js environments, with capabilities that depend on the selected backend and model.

Developers can use it for suitable classification, prediction, and computer vision workloads. Before using it in production, evaluate model compatibility, runtime performance, hardware support, and whether a JavaScript-based implementation meets the project’s needs.

2. Brain.js

Best for: Smaller neural network experiments and learning projects.

Brain.js is a JavaScript library for working with neural networks. It can be useful for learning the basics of neural network development and experimenting with comparatively straightforward problems.

It is not a replacement for every modern machine learning framework. Review its current maintenance status, supported operations, and performance limitations before selecting it for a business-critical application.

3. Synaptic

Best for: Exploring neural network architectures in JavaScript.

Synaptic is a JavaScript neural network library that has been used for building and experimenting with network architectures. It may be relevant for educational work or existing projects that already depend on it.

Because library maintenance and ecosystem compatibility can change, check the repository, recent releases, documentation, and dependencies before using Synaptic in a new production system. For larger or more specialized workloads, compare it with actively supported alternatives.

4. Natural

Best for: Traditional natural language processing in Node.js.

Natural is a JavaScript natural language processing library that provides utilities for tasks such as tokenization, stemming, classification, and other text-processing operations. It can be useful when an application needs language-processing functionality without relying on a large generative AI model for every task.

Potential use cases include categorizing support messages, processing text, and building rule-based or statistical language workflows. Verify language support and the availability of the required algorithms for your specific application.

5. ml5.js

Best for: Accessible machine learning experiments and creative projects.

ml5.js provides a higher-level interface to selected machine learning capabilities, with a focus on making machine learning more approachable for creative coding and educational projects. It builds on web machine learning technologies and can simplify certain model-based interactions.

Its suitability for a Node.js backend depends on the specific feature and runtime support. Check the current documentation before assuming that a browser-focused example will work unchanged in a server environment.

6. Neuro.js

Best for: Evaluating existing JavaScript machine learning projects.

Neuro.js has been associated with JavaScript machine learning and intelligent application development. Its relevance to a new project depends on the current state of its repository, documentation, dependencies, and supported use cases.

Before choosing it for a production application, verify that it is actively maintained and meets your security, compatibility, and performance requirements. If those requirements are not met, consider a better-supported library or a hosted AI service.

7. Compromise

Best for: Lightweight English-language text analysis.

Compromise is a JavaScript library for processing and analyzing natural language. It can help applications identify and work with elements such as nouns, verbs, dates, and other text structures using lightweight language-processing techniques.

It is useful for selected text-processing tasks, but it is not a general-purpose machine learning framework or a substitute for a large language model. Check its current language coverage and capabilities against your requirements.

8. Keras.js

Best for: Assessing existing projects that use browser-based model execution.

Keras.js was developed to run certain trained neural network models in JavaScript environments, particularly in the browser. It may be relevant when maintaining an older project that already uses it.

For new projects, carefully verify its current maintenance, compatibility with modern model formats, and supported runtime. Teams should compare it with actively supported alternatives before committing to it for a production deployment.

9. OpenAI Node.js SDK

Best for: Connecting Node.js applications to OpenAI APIs.

The OpenAI Node.js SDK is a client library for communicating with OpenAI services from JavaScript and TypeScript applications. It can be used to integrate supported API capabilities into applications, depending on the models and endpoints available to the account.

Typical use cases include conversational interfaces, text generation, structured outputs, and other supported model capabilities. The SDK itself is not a local machine learning framework; model processing takes place through the relevant OpenAI service.

Keep API credentials on the server, handle errors and rate limits, and review usage costs, data-handling requirements, and the current API documentation before deployment.

10. face-api.js

Best for: Evaluating face-detection and facial-analysis functionality in existing JavaScript projects.

face-api.js provides JavaScript implementations for selected face-detection and facial-analysis tasks built on TensorFlow.js. It has been used in browser and Node.js projects, although setup requirements and compatibility depend on the runtime and model configuration.

Before using it in a new application, check maintenance activity, supported dependencies, model compatibility, and performance. Facial data is sensitive, so any deployment should also address consent, privacy, security, and applicable legal requirements.

Need help selecting a production-ready AI stack? Read about web performance with Node.js development services and consider how application architecture affects your AI workloads.

How to Choose the Right Node.js AI Library

Choosing a library should begin with the business problem, not the popularity of a package. A chatbot, a document classification workflow, and a custom image model can require very different tools and infrastructure.

1. Define the AI Use Case

Determine whether your application needs text analysis, generative AI, image processing, recommendations, prediction, or another capability. A clearly defined use case makes it easier to shortlist appropriate libraries and test their results.

2. Decide Between Local Models and Hosted AI APIs

Local inference may offer greater control over execution and data flow, but it also requires suitable model support, compute resources, deployment planning, and maintenance. Hosted APIs can simplify access to capable models, but introduce external dependencies, usage costs, latency considerations, and provider-specific data policies.

3. Check Maintenance and Compatibility

Review release activity, issue handling, documentation, supported Node.js versions, dependency health, licensing, and security advisories. A library that works for a prototype may not be the right choice for a system that needs long-term support.

4. Test Performance with Realistic Workloads

Benchmark latency, throughput, memory usage, and operating costs with representative data. For API-based AI, measure network and provider response times as well as the time spent in your own application. For local inference, test the model and runtime on the hardware intended for deployment.

5. Plan Security, Privacy, and Monitoring

Assess whether the application processes personal, confidential, or regulated information. Apply appropriate access controls, protect credentials, validate model outputs, and log operational metrics without unnecessarily exposing sensitive data. Add human review where an incorrect AI result could create material risk.

Common Business Use Cases for Node.js AI Integration

Node.js can act as the application layer that connects AI capabilities with business data, user interfaces, and operational systems. Examples include:

  • Customer support assistants: Connect chat interfaces to an AI API and approved knowledge sources, with escalation paths for complex requests.
  • Document processing: Extract, classify, or summarize information from business documents using suitable models and validation steps.
  • Recommendation features: Combine product or user data with a suitable recommendation model or external service.
  • Text classification: Categorize messages, feedback, or support tickets using traditional NLP tools or machine learning models.
  • Workflow automation: Route requests, extract fields, and prepare suggested actions while retaining appropriate approval and audit controls.
  • Computer vision applications: Connect compatible image-processing models or services to a Node.js API for supported visual tasks.

These are implementation patterns, not guarantees of business results. The appropriate model, data source, evaluation process, and system design depend on the application’s goals and constraints.

Why Work with a Node.js and AI Integration Partner?

Choosing a library is only one part of building a dependable AI-enabled application. Production systems also require architecture planning, API integration, authentication, data handling, error management, performance testing, deployment, and ongoing monitoring.

A development partner can help assess whether a hosted model, JavaScript library, or separate inference service is appropriate for the project. This evaluation can reduce avoidable integration work and ensure that the technical approach matches the business requirements.

When evaluating a development partner, ask how they handle model evaluation, API security, cost controls, data privacy, observability, and maintenance. Request a clear implementation scope and measurable acceptance criteria rather than relying on broad claims about AI capabilities.

Looking for support with your project? Explore Mindpath’s Node.js development services to discuss your application architecture, integrations, and development requirements.

Conclusion

Node.js libraries for AI give development teams several ways to add intelligent capabilities to JavaScript applications. Tools such as TensorFlow.js, Natural, and Compromise support different types of local processing, while the OpenAI Node.js SDK connects applications to hosted AI services. Other libraries may be useful for existing projects, but their current maintenance and compatibility should be checked before adoption.

The right choice depends on your business use case, model requirements, data policies, performance targets, and long-term maintenance needs. A well-planned integration should include testing, security controls, monitoring, and a clear way to measure whether the feature meets its intended purpose.

At Mindpath, we support businesses building and integrating digital solutions. Visit our Node.js development services page to discuss your project requirements and explore an implementation approach aligned with your business goals.

Discover top Node.js libraries for AI integrations and learn to enhance your applications with machine learning, NLP, and more.