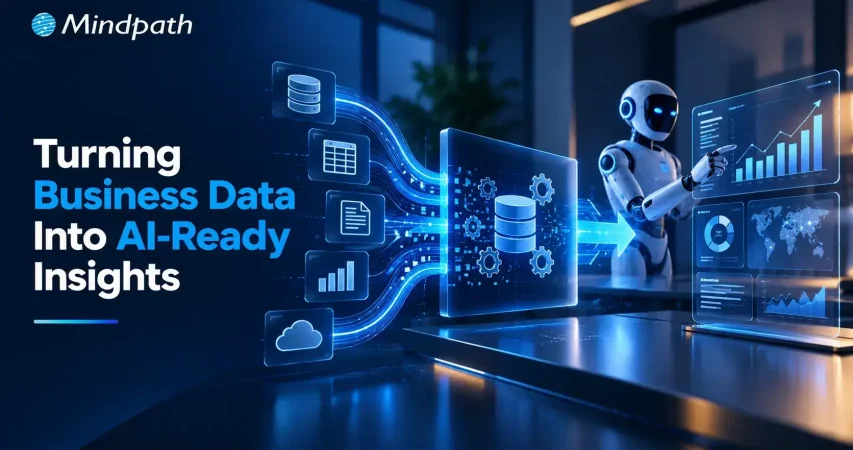
Business data holds valuable insights, but poor quality, scattered records, and inconsistent formats can make those insights difficult to unlock. When businesses introduce AI without addressing these issues, even capable models can produce unreliable results. The real challenge is making existing data accurate, relevant, and usable for meaningful business decisions.
Key Takeaways
- 01
Assess existing data sources to identify gaps, inconsistencies, and information needed for specific AI applications. - 02
Clean and validate records to improve data reliability and reduce misleading AI outputs. - 03
Transform business data using suitable encoding, feature engineering, and formatting techniques. - 04
Prepare documents for AI retrieval using text extraction, chunking, embeddings, and metadata. - 05
Maintain reliable data pipelines with automated quality checks, governance, and continuous performance monitoring.
Data preparation for AI helps bridge this gap by turning raw information into reliable inputs for AI applications. From correcting data inconsistencies to organizing documents for generative AI applications, each step influences the quality of the outcome. In this blog, we will cover the practical steps to prepare business data for AI and build a reliable foundation for long-term success.
Need support with your AI data strategy?
Our AI data consulting services can help organizations prepare their data foundations and move forward with greater confidence.
Understanding Your Business Data Before AI Implementation
Before preparing data for AI, businesses need a clear picture of the information they already have. Customer records, sales reports, transaction histories, and support conversations often sit across different platforms. Understanding where this data lives and how it is maintained helps identify what is useful, what needs improvement, and what is missing.
Start by reviewing your data sources, formats, volume, and frequency of updates. Exploratory data analysis (EDA) can reveal missing values, unusual patterns, inconsistent entries, and relationships between variables. These findings help teams assess whether the available information can support the intended AI application.
Business goals should guide this assessment. For example, a retailer planning to forecast product demand needs reliable sales history, inventory records, and information about seasonal promotions. Missing or inconsistent records could affect the quality of its predictions.
This initial review also helps teams identify access restrictions, data ownership issues, and gaps in historical records. These factors matter when planning AI-driven data analytics and deciding which datasets are suitable for a specific use case. A focused assessment gives businesses a practical starting point and prevents time and resources from being spent preparing irrelevant information.
How to Prepare Business Data for AI Applications?
Once businesses understand their existing data, the next step is to improve its quality and consistency. Data collected across different systems often contains missing values, duplicate entries, outdated records, or conflicting formats. Addressing these issues early helps AI models work with dependable information and reduces the risk of misleading results.
The following practices make data preparation for AI more effective:
1. Handle Missing Values
Identify incomplete records and decide whether to fill gaps, retain them with appropriate indicators, or remove affected entries. The right choice depends on the data and its intended use.
2. Correct Inconsistent Formats
Standardize dates, currencies, measurement units, naming conventions, and data types so information from different sources can work together.
3. Remove Duplicate Records
Find repeated entries without accidentally deleting legitimate transactions or multiple interactions associated with the same customer.
4. Identify Errors and Outliers
Investigate unusual values before removing them. An unexpected transaction or sudden change in demand may reflect a genuine business event rather than a data error.
5. Apply Validation Rules
Check required fields, acceptable value ranges, and relationships between connected records. Repeat these checks whenever new data enters the system.
6. Maintain Data Traceability
Document where information comes from and how it has been changed. This helps teams investigate unexpected AI outputs and maintain confidence in the underlying data.
Steps to Make Business Data AI-Ready Through Transformation
With data cleaned and validated, the next step is to transform it into a format that suits the intended AI application. Raw information often needs restructuring before a model can identify patterns, make predictions, or generate useful responses. The right transformations depend on the data type, the model, and the business objective.
The key steps to make business data AI-ready include:
1. Standardize Numerical Data
Adjust the scale of numerical values when needed. For example, a machine learning model analyzing customer age and annual income may benefit from scaling because these variables have very different ranges.
2. Encode Categorical Information
Convert fields such as product categories, customer segments, and payment methods into representations that the selected model can process.
3. Create Meaningful Features
Derive useful variables from existing records. A retailer, for instance, can calculate average monthly sales or purchase frequency to help a forecasting or customer behaviour model identify relevant patterns.
4. Structure Data for Training
Organize records into suitable training, validation, and test datasets. Keep information that would not have been available at prediction time out of the training process to prevent data leakage.
5. Preserve Relevant Context
Retain important relationships between fields and records instead of flattening the dataset in ways that remove useful business information.
Preparing Unstructured Data for AI Applications
Structured data, such as sales figures and customer records, is only one part of a business’s information. Emails, PDFs, contracts, product manuals, and support conversations often contain valuable context that AI systems can use. However, this information needs additional processing before it can support reliable search, analysis, or generative AI applications.
Key considerations when preparing data for AI include:
1. Extract Text from Documents
Use parsing tools to retrieve content from PDFs, Word files, and emails. Apply optical character recognition (OCR) to scanned documents and images containing text.
2. Remove Irrelevant Content
Eliminate repeated headers, broken characters, and redundant material while preserving important details and the original meaning.
3. Divide Content into Meaningful Chunks
Split lengthy documents into smaller, related sections. Appropriate chunk sizes help retrieval systems find relevant information without losing essential context.
4. Generate Embeddings for Semantic Search
Convert text into numerical representations that help systems identify content with similar meanings. This is particularly useful for embeddings and retrieval-augmented generation (RAG).
5. Preserve Metadata and Permissions
Retain details such as document source, date, category, and access restrictions so AI systems can retrieve relevant information without exposing unauthorized content.
Building a Reliable Data Pipeline for AI
Once structured and unstructured data are prepared, businesses need a reliable way to keep that information updated and consistent. A one-time cleanup cannot account for new records, changing business requirements, or unexpected changes in data formats. A well-designed data pipeline automates recurring tasks and maintains data quality as AI applications evolve.
Key elements of a reliable pipeline include:
1. Automate Data Ingestion
Collect information from business applications, databases, APIs, and document repositories through scheduled or event-driven workflows.
2. Run Continuous Quality Checks
Validate incoming records for missing fields, duplicates, format changes, and inconsistent values before they reach AI systems.
3. Establish Data Governance
Define data ownership, access permissions, retention rules, and privacy requirements to protect sensitive business information.
4. Monitor Data Freshness and Drift
Track how frequently datasets are updated and identify changes that could affect model performance.
5. Maintain Data Lineage
Record where information originates and how it moves through the pipeline, making errors easier to investigate.
6. Design for Future Growth
Build infrastructure that can accommodate additional data sources, increasing volumes, and new AI use cases without requiring a complete redesign.
Businesses can use AI data engineering services to build and maintain these pipelines, integrate disconnected systems, and establish dependable data workflows that support their growing AI requirements.
Measuring Data Quality and AI Readiness
A reliable data pipeline helps maintain consistency, but businesses also need to measure whether their data is ready to support the intended AI application. Regular evaluation helps teams identify weaknesses early, prioritize improvements, and understand how data quality affects model performance.
Businesses can assess their progress through a few practical measures:
1. Data Completeness
Track the percentage of records containing all required fields for the intended use case.
2. Data Accuracy
Compare selected records against trusted sources to identify incorrect values and inconsistencies.
3. Data Freshness
Measure how recently information was updated, particularly for applications that depend on current business data.
4. Model Performance
Evaluate relevant metrics, such as forecast error, precision, recall, or retrieval relevance, based on the AI application.
5. Business Impact
Monitor changes in decision-making time, manual effort, prediction reliability, or customer support efficiency.
Ready to Make Your Business Data AI-Ready?
Successful AI adoption begins with reliable data. From assessing existing records and correcting inconsistencies to transforming information and maintaining quality, data preparation for AI helps businesses build dependable applications. A structured approach allows teams to reduce data-related risks, improve model performance, and make informed decisions as their AI needs grow.
Mindpath offers AI development services to help businesses build practical, scalable AI applications backed by reliable data infrastructure. Our AI data consulting services and data engineering expertise help organizations prepare their data foundations and move forward with greater confidence. Connect with Mindpath to discuss your AI goals.